Achieving high-availability and 24x7 banking services
Recent incidences of banking and e-payment outages have raised the question – what will it take to ensure failproof services?
MISSION-CRITICAL applications are designed to have redundant components so that when one part fails, the backup component is activated to allow the application to continue with little or no interruption. Whether it’s a critical service like banking or ensuring flight safety on an aircraft, we often take for granted the redundancies that make these services resilient to the failure of any one component. In an aircraft, for example, the rudder (the movable part of the aircraft at the back of the fin) allows the plane to turn left or right. The rudder is a critical component and hence is controlled by three separate hydraulic systems to provide the required redundancy in case of failure.
When it comes to banking, the key difference is that there are multiple components, likely located in different geographical locations, that must be switched over in tandem for redundancy to work.
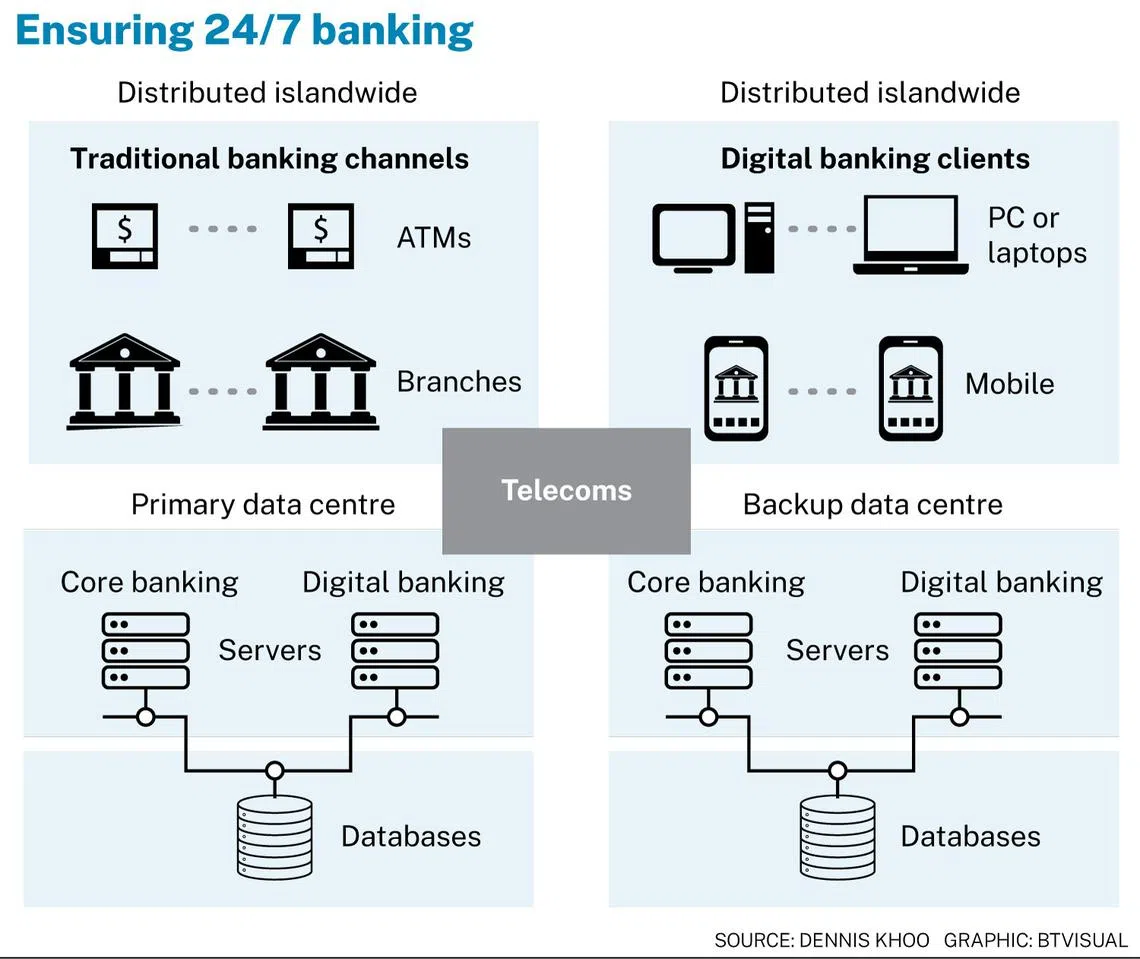
The figure above is a simplified diagram of the essential components required to provide high availability of banking services. The primary data centre houses the core banking servers and databases necessary to provide your everyday banking services. In the event that the primary data centre is inoperable, a backup data centre located in a different location – or for even greater redundancy, in a different country – will take over to provide banking services.
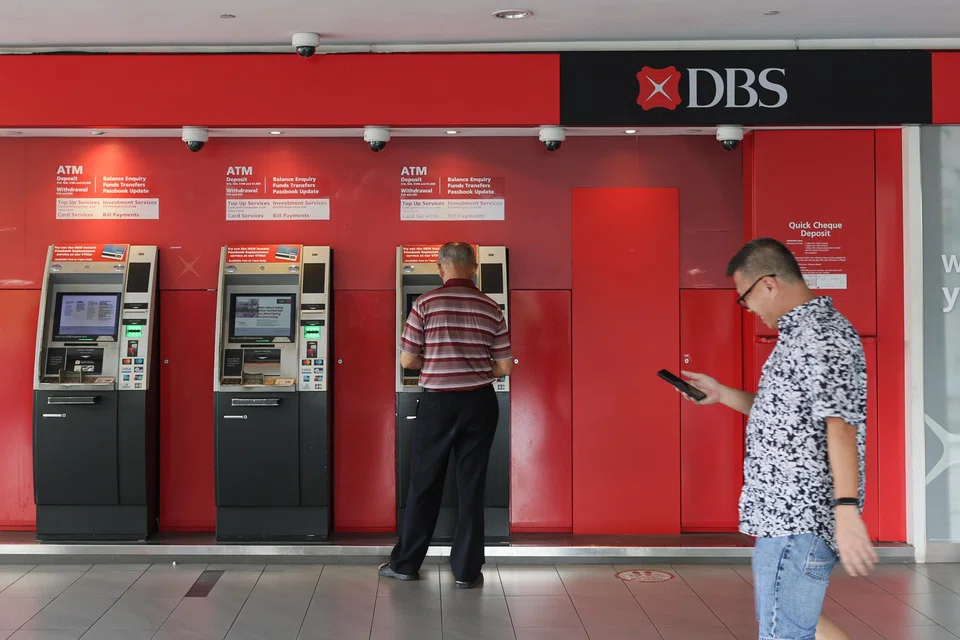
These data centres are connected to traditional banking channels, such as ATMs or physical bank branches, and to mobile phones, laptops and personal computers commonly used to access digital banking services. The connections – between the primary and secondary data centres or between these data centres and the traditional or digital banking channels – take place over telecommunications networks. Thus, to achieve the required redundancy, all these components must be made redundant.
In Singapore, the regulator stipulates a limit of no more than four hours of downtime within 12 months or 99.95 per cent system availability. A system with 99.95 per cent availability is considered highly reliable, making it suitable for mission-critical applications. To achieve such high availabilities, all four components of the banking applications shown in the figure must be designed to have redundancy:
- The data centres with the core banking applications and databases have primary and backup data centres both equipped with the necessary services and equipment.
- ATMs and branches already have some redundancy as they are distributed over a wide area, so that if an ATM or branch is not functioning, a nearby ATM or branch can take its place.
- The digital banking servers that communicate with apps that run on mobile phones, personal computers or laptops must be redundant.
- The telecommunications infrastructure must leverage multiple telcos and redundant networking equipment to ensure that if a telco or networking equipment fails, another telco or backup networking equipment is always able to stand in to ensure every component can communicate with another component end-to-end.
Unlike the airplane example however, banking applications can resume only if all the four components above are able to switch to the redundant stand-by service or equipment if a failure occurs; and upon switching over, all four components must be able to communicate with each other to deliver the required end-to-end banking service.
As not all components may experience a switch-over, the components that are switched over and running on backup must be able to communicate with components that are still operating normally. This creates multiple permutations of primary and backup scenarios where all required components must be able to communicate with each other during a possible failure of any component. Some of these permutations include:
- The primary data centre fails and the backup data centre takes over. For banking services to resume, all existing ATMs, branches and digital banking servers must be able to connect to the backup data centre and databases. This is not instantaneous, as several steps are involved – a fault-detection system must first detect that a failure has occurred and the switchover must be initiated. Various components then need to be brought online, and connectivity between all four components must be established before banking services can resume.
- If the connectivity between any of the four components has an issue, significant troubleshooting to isolate and replace the faulty component may delay the eventual uptime.
- There may be circumstances where crucial equipment in both the primary and backup systems fail to communicate due to configuration issues, updates in equipment firmware or operating systems that create incompatibilities in the components involved in providing the end-to-end solution.
Banks are required to simulate failover scenarios to test that all required components switch over in a manner that allows recovery of all services within an acceptable window should an outage occur.
It’s not good enough just to designate a primary and a backup data centre. An advanced method to further reduce downtime in the event of an outage is to have multiple primary data centres, where multiple servers are actively serving customers, and thus when one data centre fails, the other data centres simply experience a greater load. Such configurations are however more costly, and even more complex to troubleshoot.
Through proper design and configuration, banking service disruptions can be kept to a minimum in the best-case scenarios, in the event of an outage. However, it is not as straightforward as having a spare phone if your phone is not operable.
The writer is a former senior executive in IT and banking, and author of Driving Digital Transformation – Lessons from Building the First Asean Digital Bank